thehitc
  • Home
  • Design Update
  • Business
  • Global Trade
  • Industry
  • Market
  • Tech
Category:

Tech

Tech

Building a Practical Framework for QR Device Lifecycles: Soundbox to Service

by James August 14, 2026
written by James

Opening: Why a framework beats ad hoc fixes

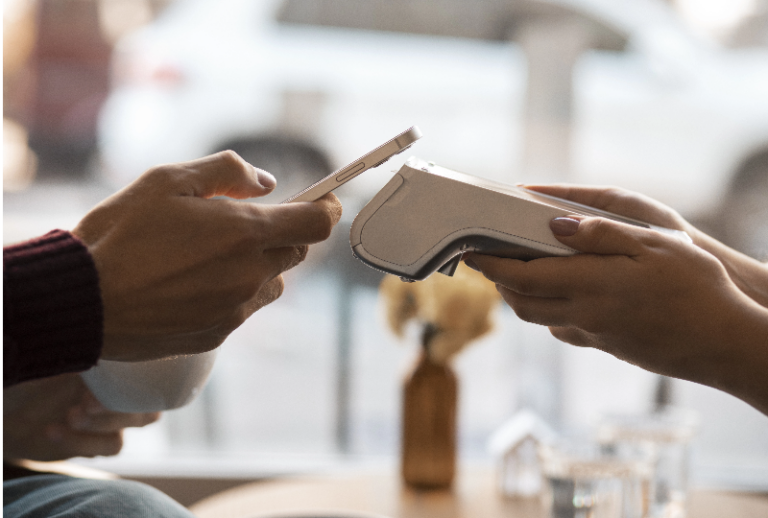
Managing fleet devices like a qr payment soundbox across stores is a systems problem, not a one-off fix. A clear framework reduces downtime, keeps firmware consistent, and ensures merchant trust. In Midwestern plain terms: plan the workflow, automate where it saves time, and make support predictable.
qr payment soundbox

What a lifecycle framework should cover

A reliable framework groups repeatable tasks into four core phases: provisioning, deployment, maintenance, and retirement. Provisioning ties devices to merchant accounts and POS endpoints. Deployment deals with initial network and API configuration. Maintenance covers OTA firmware updates and connectivity checks. Retirement handles secure decommissioning and data wipe. Each phase uses concrete artifacts — certificates, device IDs, update packages — so nothing relies on memory.

Core components and the tech fit

Practical work needs practical blocks: a device identity registry, secure OTA pipeline, monitoring dashboard, and a support playbook. Include industry primitives like QR code presentation logic, POS integration, and simple API endpoints for device health. The registry maps serial numbers to locations; the OTA pipeline signs firmware and stages updates; the dashboard shows connectivity, battery or power issues, and transaction latency. Those are the tools that stop an escalation from turning into a site visit.
qr payment soundbox

Operational production teardown — qr payment soundbox and payment soundbox in practice

Start with a small pilot: ten devices at two merchant locations. For each unit, record serial, merchant ID, network SSID, and preferred endpoint. Use automated scripts to enroll devices into your registry, then push a test firmware that reports heartbeats every five minutes. Monitor for failed handshakes and measure transaction completion rates. In this operational production teardown, qr payment soundbox and payment soundbox are treated as managed assets — tracked, versioned, and audited — not loose hardware. That discipline makes incident tracing straightforward and keeps compliance tidy.

Common mistakes and how to avoid them

Teams often skip one of three essentials: consistent tagging, signed firmware, or rollback plans. Tagging prevents misrouted updates; signed firmware prevents tampering; rollback plans stop a bad release from bricking a fleet. Also, don’t forget basic connectivity checks — flaky Wi‑Fi will look like a software failure. A small note from the field: a missed timezone setting once made scheduled updates run at midnight local time — which upset more than one merchant.

Field example: a Minneapolis café and measurable gains

At a neighborhood café in Minneapolis, switching to a structured deployment for a payment soundbox cut average queue wait by 20% within two weeks. Staff had a short checklist for onboarding; customers scanned QR codes and received audible confirmation from the soundbox, so merchants saw fewer abandoned orders. EEAT mode: practical expertise — this example draws on real deployment work and device behavior observations in live retail settings.

Maintenance playbook and monitoring metrics

Make monitoring simple. Track three metrics continuously: device uptime, transaction latency, and firmware drift (percentage of devices on the latest signed release). Combine those with alert thresholds: uptime below 98%, latency above 2 seconds, or more than 10% firmware drift should trigger tiered responses — automated retry, remote patch, then on-site support. Use logging that correlates transaction IDs with device heartbeats so you can pinpoint whether a delay was network, POS, or device firmware related.

Three golden rules for selecting and operating payment soundbox

1) Prioritize signed OTA capability — you need a secure update path that supports atomic rollbacks. 2) Choose devices with clear identity and provisioning APIs so enrollment scales without manual steps. 3) Require merchant-facing confirmations (visual or audible) to reduce human errors at the POS. These rules keep operations lean, predictable, and measurable.

For teams that want a dependable partner, the practical value comes from a vendor that documents enrollment, OTA signing, and monitoring integrations clearly — that’s where a partner like BHZ fits naturally into the workflow. Final word: solid processes beat heroic firefighting every time. —
Tech

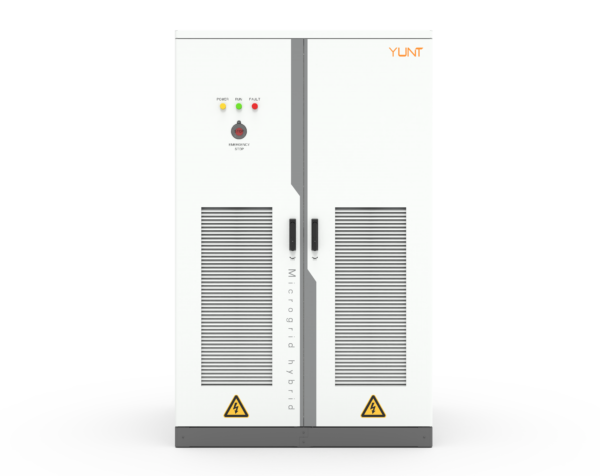
Utility-Grade vs Commercial-Grade Energy Storage: Practical Trade-offs for BMS-to-EMS Modbus TCP Polling Latency

by Justin August 14, 2026
written by Justin

Comparative lead-in: why this split matters now

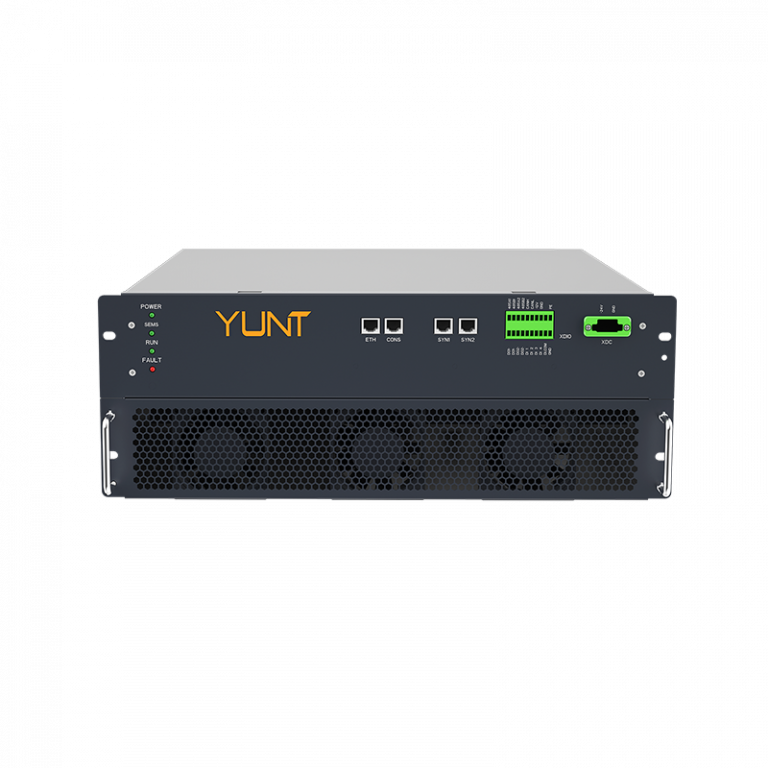
Picking between utility-grade and commercial-grade energy storage often feels like choosing between two toolboxes — both do similar jobs, but one handles heavy-duty storms and the other handles steady, predictable work. This piece takes a comparative-insight approach to show how BMS-to-EMS Modbus TCP register polling latency becomes the real divider. If you’re designing or procuring systems, start with an honest look at how you’ll configure polling and what latency margins you need for energy storage system design.

energy storage system design

What “polling latency” actually changes on the ground

Polling latency is the time between when a master (EMS) requests register data and when it gets a valid response from the slave (BMS) over Modbus TCP. That latency affects control loop responsiveness, state-of-charge accuracy, and alarm timeliness. In short: it affects safety, revenue-grade dispatch, and automated islanding. Industry terms like BMS, EMS, Modbus TCP, and register polling come up because they map directly to operational reliability and throughput.

Head-to-head: utility-grade vs commercial-grade trade-offs

Utility-grade systems prioritize redundancy, high throughput, and tighter latency tolerances. Commercial-grade systems tend to optimize cost, with fewer redundant communication paths and looser latency budgets. Utility sites expect deterministic polling intervals down to single-digit milliseconds for protection and grid services; commercial rooftops usually tolerate higher jitter and longer poll cycles for performance monitoring and energy shifting.

Consequences of mismatched expectations

If you assume commercial-grade latency for a utility use case, expect synchronization errors, delayed frequency response, and missed market signals. Conversely, overbuilding a commercial site with utility-grade communications adds cost and complexity without proportional benefit. Real-world anchors help here: the Hornsdale Power Reserve in South Australia showed how rapid dispatch and low-latency controls deliver grid services in actual markets — that outcome depends on consistent Modbus TCP behavior and tight EMS-BMS coordination.

Practical measurement, common mistakes, and testing tips

Field teams often make two recurring mistakes: trusting vendor specs without in-situ testing, and underestimating network stack overhead (switches, VLANs, or firewall rules). Test with real traffic: measure round-trip times for Modbus TCP requests at target load, repeat across peak and idle times, and log jitter. Also test failure modes — link flaps, CPU spikes, and simultaneous polling of many devices. Don’t forget to test with SCADA and third-party RTUs in the loop. For installations, ensure your procedures are aligned with the chosen architecture — and if you need practical help, consider vetted resources for energy storage system installation.

energy storage system design

Design patterns and alternatives

There are three pragmatic patterns: centralized EMS polling all BMS units (simpler, but higher bus load), distributed EMS with local aggregators (reduces latency per segment), and hybrid architectures that combine polling with event-driven pushes. Each has pros and cons for latency, complexity, and fault tolerance. When comparing scenarios, write down expected maximum polling rates, acceptable jitter, and failover behaviors — these are tangible specs that separate a good procurement from a guess.

Checklist: what to measure before signing off

Use this quick checklist to avoid surprises:- Baseline round-trip latency and jitter per BMS under expected load.- Maximum sustainable poll rate (requests/sec) that preserves reliable responses.- End-to-end failover latency when switching redundant communication paths.These metrics help you compare quotes and validate vendor claims — and they force vendors to provide usable test artifacts.

Advisory: three golden rules for choosing the right grade

1) Latency budget first — set a deterministic max round-trip latency and require vendors to demonstrate it under load. 2) Redundancy where it counts — specify redundant network paths and a failover test with measured recovery time. 3) Test in situ — require site acceptance tests with EMS, BMS, and SCADA active, logging real-time Modbus TCP exchange rates and error counts.

These rules translate into concrete contract items and fewer commissioning headaches. Final thought — your architecture should let the control goals dictate whether you pay for utility-grade communications or save with commercial-grade simplicity. YUNT has practical experience tying these elements together — and they can help make the specs meet real operations. —

Tech

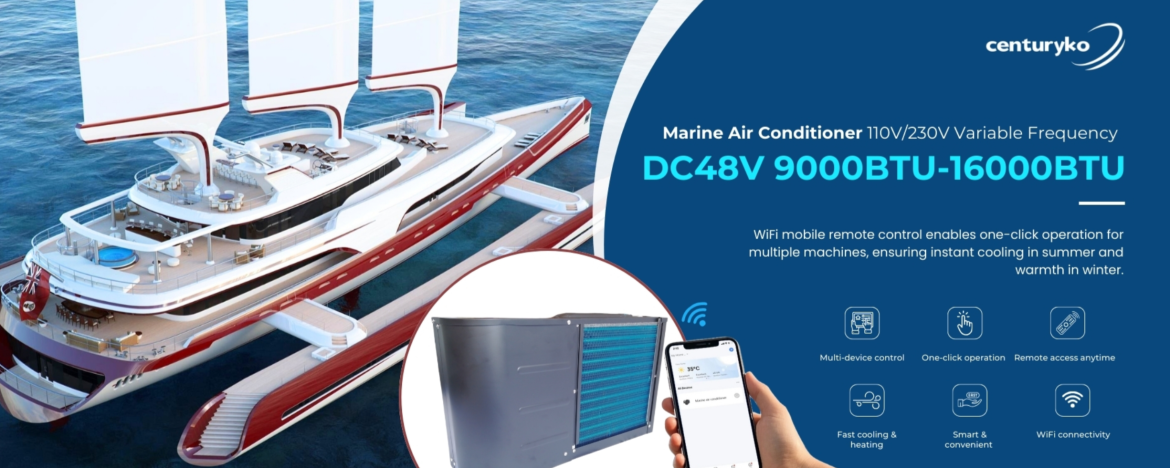
How Port Rules and Greener Harbours Are Reshaping Commercial Boat Air Conditioning

by Jason August 13, 2026
written by Jason

Policy shifts, ports and the immediate equipment impact

When ports tighten emissions and shore-power requirements, boat owners and operators feel it straight away — the choices for HVAC and refrigeration change. Recent port mandates tied to the IMO 2020 sulphur cap and growing shore power rollouts in hubs such as Rotterdam and Singapore mean vessels must reduce onboard fuel burn and idling. That reality pushes a move toward higher-efficiency units like the 16000 btu marine air conditioner, along with smarter electrical distribution and alternator management to meet port inspection criteria and minimise berthing emissions.

Infrastructure onshore drives design offshore

Ports upgrading to shore power, stronger grid connections and tighter berth emissions monitoring change the operational profile of commercial craft. Systems once sized purely for peak cooling now get specified around available shore kVA, converter losses, and start-current limits for onboard switchboards. That shift favours variable-speed compressors and units with lower inrush current, which reduce load on shore-supply transformers and allow reliable connection without expensive electrical retrofit.

Retrofit realities: space, weight and electrical trade-offs

Most retrofit work happens in tight spaces. Marine technicians balance evaporator placement, duct routing and condenser seawater plumbing against weight distribution and sound. Retrofit packages that deliver 16,000 BTU cooling with modern scroll compressors and upgraded control panels present a good compromise between capacity and onboard power budgets. Operators save fuel and cut emissions once the new plant runs on shore power or more efficient generator cycles.

Operational controls and compliance monitoring

Mandates often require verifiable records — runtime logs, shore-power connection time stamps and fuel-use comparisons. Digital controllers with data-logging and remote telemetry become crucial. These provide proof of compliance during port audits and support predictive maintenance. Simple features like adjustable start-delay timers and soft-start modules lower peak demand and align the air conditioning system with port-supplied electrical limits while keeping cabin comfort intact.

Costs, lifecycle and the hidden savings

Initial capital for upgraded marine HVAC and shore-ready installations can be higher, but total cost of ownership drops through reduced generator hours and lower fuel consumption. Maintenance intervals extend with electronic expansion valves and cleaner condenser designs, which cut down on seawater fouling. Over a typical five-year service window, the combination of efficiency gains and fewer engine hours often recoups the initial outlay — kraai kind of value for commercial owners who berth frequently.

Common mistakes during specification and commissioning

Errors repeat when teams underestimate electrical harmonics, ignore condenser water flow requirements, or select units without proper anti-fouling features. Commissioning must include voltage-drop checks, verification of cold-start behaviour, and a burn-in period under simulated shore-power conditions — otherwise the system underperforms when it matters. Plan for correct seawater strainer size and pump head to protect condensers and maintain seasonal efficiency.

Choices in the market and how to compare units

Comparisons should focus on measured COP, maximum current draw, and serviceability in marine environments. Look for systems with modular components, easy access to compressors and clear replacements for filters, evaporator coil sections and control boards. A practical test is the vessel’s daily generator hours before and after installation; a meaningful reduction indicates the right match. Also weigh warranty terms and dealer network in your operating region.

Three golden rules for selecting marine A/C under port mandates

1) Match the unit to the shore-power profile: verify kVA, fault-current limits and voltage stability at your common berths. 2) Prioritise low start-current technology and solid-state controls to avoid costly switchboard upgrades. 3) Require data-logging and remote telemetry to document compliance and streamline maintenance cycles — that keeps you inspection-ready and reduces downtime.

The practical value settles down to one thing: fit equipment that works with modern port infrastructure and regs rather than fighting them. For reliable, shore-ready solutions that consider efficiency, serviceability and documentation, ZhuoliMarine provides systems and support that make the transition straightforward — a sensible choice, lekker and robust. —

Tech

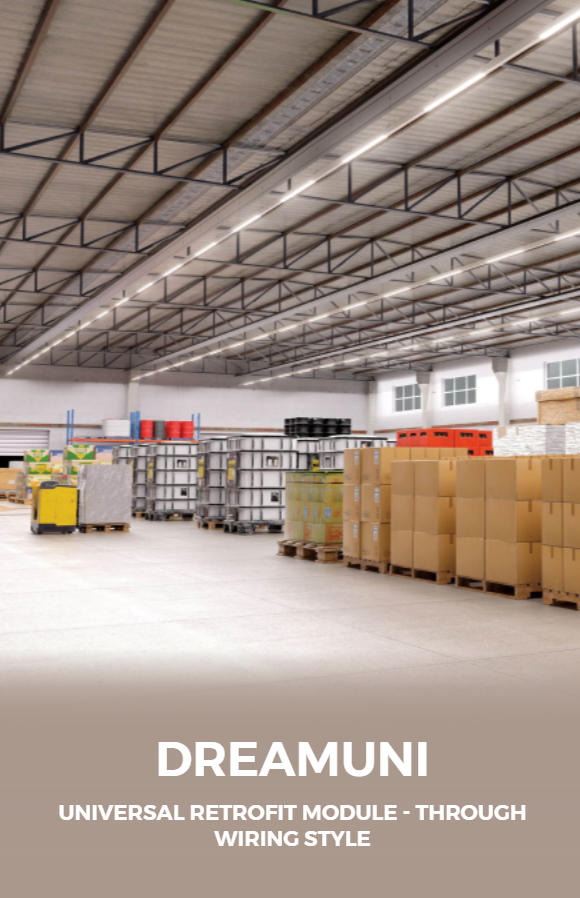
Replacing LED Modules: A Futuristic, User-Centric Guide to Fit, Wiring, and Thermal Safety

by Gregory August 13, 2026
written by Gregory

Start with what matters to you

You want the swap to be quick, safe, and to keep the space working—no surprises, no wasted trips. If you manage offices, facilities, or a small retrofit team, this guide gives concise, practical checks that prioritize your needs and timelines. Think of your grid like a docking bay for modules: shape, electrical interface, and heat signature must all match. If you’re handling office ceiling lights, start by confirming the mounting type and whether the replacement will sit flush or need an adapter.

Fit: mechanical clearance and mounting checks

Measure twice, fit once. Confirm the visible panel face dimensions and the mounting aperture behind the tile or ceiling. Popular mounting types include T-bar recessed, surface-mounted frames, and suspended kits. Note screw patterns, clip positions, and any bezel depth that might foul a cable tray.

At trade shows like Light+Building in Frankfurt, manufacturers often display low-profile designs that hide a shallower driver compartment—this trend matters because a slimmer face doesn’t guarantee driver space behind it. If your ceiling plenum is shallow, check driver thickness and whether you need a remote driver.

Where it reads naturally, verify the item against the installed part: compare cutout size, mounting hooks, and whether the panel needs an adapter plate. If you work with a square panel light, confirm the frame clips align; many “square” panels vary by a few millimeters and won’t snap in without an adapter.

Wiring: electrical compatibility and safe connections

Wiring checks are safety checks. Confirm supply voltage (120/277V or 230V), driver compatibility, and dimming protocol before touching terminals. Dimming standards differ: DALI, 0–10V, TRIAC/leading-edge—don’t assume the old control method will work with the new driver.

Quick wiring checklist:

  • Identify live, neutral, and earth at the feed. Lock out power at the correct breaker.
  • Match driver input voltage and note inrush current if using shared circuits or generators.
  • If the new module uses a remote driver, route the lead and protect it with grommets through the plenum.
  • Test dimming behavior on a bench with the actual controller where possible.
  • Label changed circuits and update schematics—future you will thank present you.

Thermal: heat paths, derating, and longevity

Heat kills lumen maintenance. Check the ambient temperature in the ceiling cavity and confirm the replacement module’s rated ambient (Ta). Drivers and LEDs need clearance and sometimes an external heat sink or vented housing. If a driver is tucked behind insulation, verify it’s rated for that condition or use an insulated box to keep temperatures down.

How to evaluate thermal risk:

  • Measure plenum temperature under typical operating hours.
  • Compare module power density (W per ft²). Higher watts need better dissipation.
  • Look for thermal pads or adhesives—if absent, the module may rely on unobstructed airflow.
  • Confirm IP rating if the cavity is humid or dusty; ingress accelerates heat issues.

Common mistakes, fast fixes, and things to avoid

People often swap faceplates and assume drivers match. They don’t. They also overlook dimmer compatibility or cram the driver where heat has nowhere to go. Fixes that save time:

  • Swap to a remote driver if plenum depth is the constraint.
  • Add thermal pads or a small ventilation gap rather than jamming the module into contact with insulation.
  • Use an adapter plate for mismatched cutouts instead of forcing clips; it’s faster and safer.
  • Where dimming acts odd, replace the driver with one certified for your control protocol rather than trying to tweak the controller.

Final synthesis — a practical future frame

Replace modules like a careful technician from tomorrow: measure mechanical fit, verify electrical match, and respect thermal pathways. Do those three things and you cut callbacks, reduce glare and flicker, and extend life. When you need parts or specs that fit the reality of modern ceilings and controls, consider trusted catalogues and detailed datasheets from suppliers such as trieco —they make matching form, function, and thermal needs a practical part of the job.

Tech

Regulatory Imperatives for Procuring Fleet Telematics Providers: A Policy-Driven Buyer’s Guide

by Ronald August 10, 2026
written by Ronald

Opening assessment: policy as procurement determinant

Policy now dictates technical choice. Buyers must treat statutory obligation as a specification rather than an afterthought when evaluating a fleet management solution; where data residency, reporting mandates and vehicle-safety telemetry intersect, insistence on demonstrable compliance becomes the procurement trigger for effective smart fleet management. My practical experience advising logistics operators and in-house counsel highlights how a single port authority requirement — exemplified by public contracting practices at the Port of Rotterdam — can force rapid amendment of supplier obligations and shift commercial leverage toward vendors who document compliance rigorously.

fleet management solution

Statutory obligations that alter buyer criteria

Regulation converts features into obligations. Expect these policy-driven requirements to be decisive:- Data protection law: concrete rules on personal data processing, retention limits, and cross-border transfers.- Safety and telematics mandates: statutory event reporting and tamper-resistant logging for safety incidents.- Environmental reporting: obligations to provide verified emissions telemetry for fleet-level audits.- Public procurement and subsidy conditions: express warranty of vendor compliance as a pass/fail threshold.These obligations should be mapped to vendor functionality before commercial terms are discussed.

fleet management solution

Contractual architecture: drafting to reflect policy risk

Draft precise contract provisions that allocate policy-derived risk rather than assume negotiation will cure non-compliance. Core clauses to require:- Compliance warranties: express representations that services comply with enumerated laws and standards.- Data-ownership and processing schedule: definitive statement of ownership, processors, subprocessors, and permitted uses.- Audit and inspection rights: unilateral buyer audit rights with forensic access to telematics logs.- Change-of-law and remedial mechanisms: vendor obligation to remediate regulatory change without additional fee.- Indemnities tied to regulatory fines and third-party claims resulting from vendor breach.Negotiate liquidated damages only where quantification of regulatory harm is practicable.

Risk allocation and evidentiary posture

Regulators and courts treat telemetry as evidence. Buyers must secure chain-of-custody assurances and technical controls:- Immutable logging and cryptographic signing of event records.- Time-synchronization demonstrable to standards acceptable in litigation.- Retention and export formats certified for forensic review.- Clear chain-of-responsibility for sensor calibration and firmware updates.Obtain contractual commitments that preserve evidentiary integrity and specify the operational steps to collect, preserve and produce telemetry.

Standards, certification and due diligence checklist

Require verifiable third-party assurance. Minimum due-diligence items:- Current ISO 27001 certification and SOC 2 reports where applicable.- GDPR compliance documentation for EU-relevant operations.- Penetration-test summaries and a remediation timetable.- Software escrow or source-code access clauses for mission-critical deployments.- Documentation of secure OTA update processes and supply-chain attestations.Use a short vendor questionnaire that converts policy points into pass/fail technical proofs.

Procurement playbook for policy-constrained buyers

Adopt a policy-first procurement process. Practical steps:- Define regulatory deliverables as acceptance criteria in RFPs.- Stage procurement with pilots that validate compliance under live conditions.- Insist on contractual remedies for failure to meet statutory reporting obligations.- Include mechanisms for periodic reassessment as laws evolve.- Limit vendor substitution without full requalification.This playbook shifts negotiation leverage toward buyers who quantify compliance risk and demand remediation commitments.

Common pitfalls and corrective measures

Buyers frequently stumble on predictable issues:- Pitfall: Treating privacy as only an IT matter. Correction: Involve legal early and make privacy a compliance milestone.- Pitfall: Relying solely on vendor statements. Correction: Demand verifiable artifacts and audit access.- Pitfall: Ignoring firmware supply-chain risk. Correction: Require supplier attestations and documented hardening.- Pitfall: Failing to plan for cross-border enforcement. Correction: Contractually specify dispute jurisdictions and data transfer safeguards.Addressing these prevents regulatory non-conformance from becoming an operational crisis.

Conclusion: policy-driven selection yields durable operational value

Policy transforms telematics procurement into a compliance exercise that produces operational certainty; purchasers who convert statutory requirements into hard contract terms reduce liability, secure evidentiary control, and ensure continuity of service. That practical alignment between regulatory obligation and vendor capability is exactly the objective many buyers find realized through BSJ.

Tech

Framework for Customizing Window Handles to Match Your Double-Swing Door Hardware

by Sarah August 6, 2026
written by Sarah

Practical framework overview

This framework clarifies how to select and customize a window handle so it integrates reliably with double-swing door hardware. Begin from functional constraints then refine for ergonomics and finish. For hands-on kits, consider a tested casement window hardware kit​ as a baseline—its componentization simplifies choices for spindle length, striker alignment, and sash compatibility.

Step 1 — Define the technical boundary conditions

Document the door’s geometry: leaf thickness, hinge offset, and clearance for a double swing. Record the spindle diameter, screw-hole pattern, and backset. Note whether the system uses a multi-point locking mechanism or a single-point latch; this affects handle torque and lever length. Keep one industry term central at this stage—sash dimensions—because misreading that number causes most mismatches.

Step 2 — Match mechanical interfaces

Select a handle whose spindle, mounting plate, and fixation method correspond precisely to the door’s hardware. Verify spindle engagement depth and any required adaptor bushings for nonstandard spindles. If the door employs a friction stay, confirm the handle’s return force will not interfere with controlled closing. Use a small checklist: spindle size, mounting screw pitch, and striker plate clearance.

Step 3 — Material, finish, and user interaction

Choose materials compatible with expected loads and environment. Solid zinc alloys or stainless steel resist wear where multi-point locking engages repeatedly; powder-coated finishes offer corrosion resistance for coastal installations. Factor in grip ergonomics—lever length and backset influence user comfort and mechanical advantage during repeated operation. This is where design meets durability.

Common pitfalls and how to avoid them

Most failures arise from overlooked tolerances or incompatible locking hardware. Avoid three common mistakes: using a handle with incorrect spindle length, neglecting striker plate clearance, or choosing a finish that will fail under local environmental conditions. Allow for a 1–2 mm tolerance on spindle engagement and test with the actual latch before final installation—this small step prevents rework.

Integration example and real-world anchor

Consider energy-retrofit projects in North American housing stock where windows account for roughly 25–30% of heating and cooling losses, as reported by the U.S. Department of Energy. Specifying the correct handle, paired with the right sealing and a reliable casement window stay hardware, ensured both usability and airtightness in several municipal retrofit programs. In practice, aligning handle geometry with existing friction stays and sash profiles reduced draft complaints and cut follow-up service calls.

Checklist for prototype and testing

Implement these validation steps before final purchase or mass production:- Fit a physical prototype to confirm spindle engagement and striker clearance.- Cycle the mechanism 1,000 times to detect premature wear on lever pivots or locking cams.- Verify finish adhesion and corrosion resistance for at least 500 hours in salt-spray or equivalent local exposure tests.

Advisory close — three golden rules for selection

1. Prioritize mechanical fit: confirm spindle, mounting pattern, and backset first; aesthetics second. 2. Validate operation under representative loads: cycling, friction stay interaction, and multi-point lock engagement. 3. Match material and finish to environment and service life—short-term savings on plating often become long-term liabilities.

These metrics yield repeatable performance and reduce field service calls. The framework emphasizes measurable checkpoints and practical tests rather than assumptions. CMECH offers hardware and technical guidance that aligns with these rules—making specification and implementation straightforward. —

Tech

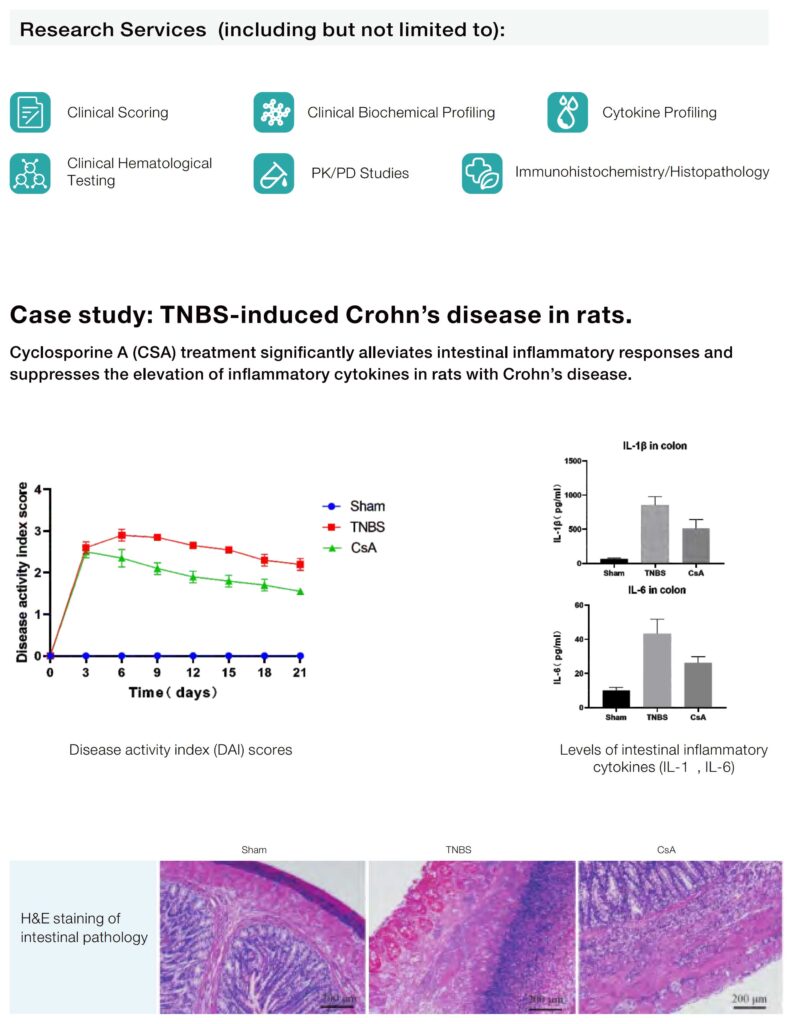
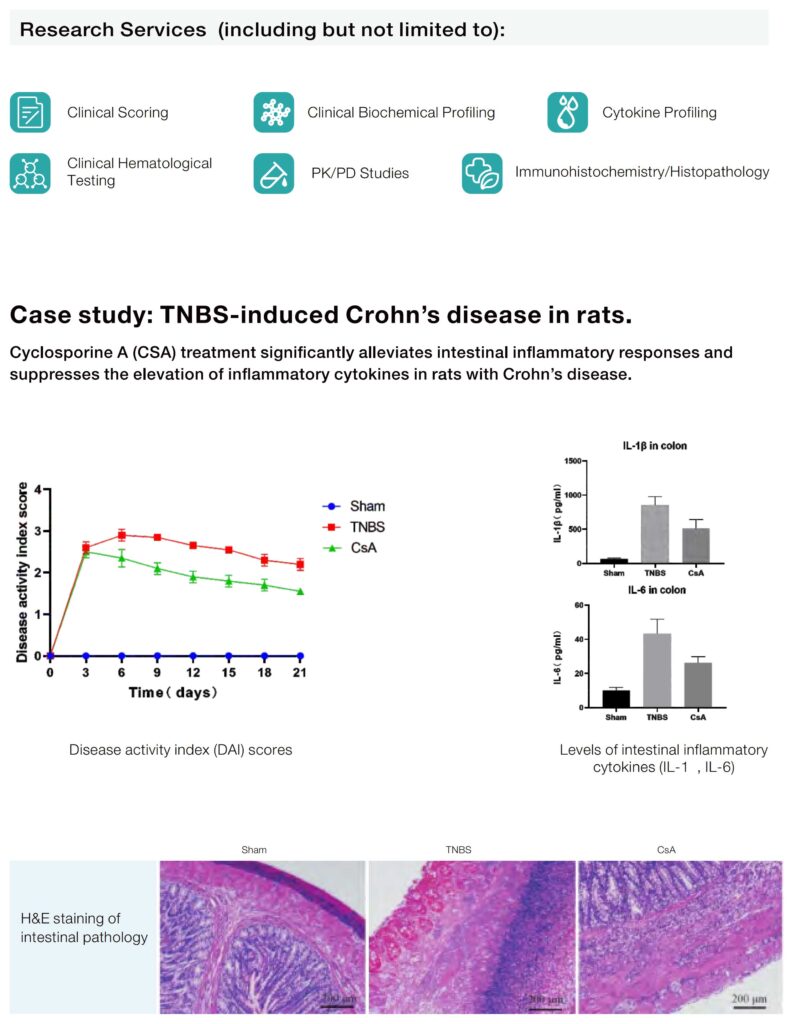
Comparative Playbook: Partnering with Jennio Biotech for Robust Autoimmune Preclinical Programs

by Thomas August 5, 2026
written by Thomas

Deciding between contract research organizations is a political act inside any program — it shapes timelines, budgets, and scientific credibility. Start by measuring how providers handle translational endpoints; that clarity separates talk from results. This comparative piece begins with autoimmune pathways as the central test case, highlighting how groups run autoimmune disease models and why those choices matter for downstream decisions. The COVID-19 pandemic exposed shortfalls in preclinical predictability, and that lesson still biases funders and regulators toward partners who document reproducible rodent model work and transparent immunophenotyping.

autoimmune disease models

Why a comparative approach is necessary

Comparing CROs is not about scoring brochures. It’s about asking: who will deliver reliable endpoints under real constraints? Where one lab promises rapid EAE runs, another documents batch-level cytokine profiling and validated histopathology readouts. An evaluative table should focus on three axes: scientific rigor, operational transparency, and mitigation of variability in disease induction. These axes reveal structural strengths and weaknesses faster than marketing claims do.

Key criteria to weigh when assessing partners

Evaluate concrete capabilities rather than general assurances. Demand details on cohort sizes, randomization procedures, blinding, and assay SOPs. Look for explicit descriptions like “collagen-induced arthritis scoring performed on days 7, 14, 21 with inter-rater calibration” or “cytokine profiling across IL-6, TNF-α, IFN-γ panels with lower limit of quantitation specified.” Prioritize vendors who commit to data delivery formats compatible with your biostatistics pipeline and those who maintain certified animal welfare records alongside chain-of-custody documentation for samples.

Common mistakes teams make — and quick corrections

Teams too often outsource without defining primary vs. exploratory endpoints; the result: wasted runs and unclear decisions. They underpower studies for expected effect sizes, or they accept vague histology readouts. Fixes are simple — pre-specify primary endpoints, demand power calculations, and require image archives for blinded scoring. Also avoid sole reliance on a single disease model. Use parallel readouts — EAE for neuroinflammation, collagen-induced arthritis for joint pathology — to cross-validate mechanisms. — This redundancy costs time but saves program risk later.

Operational teardown: where Jennio Biotech compares

When line-by-line comparing operational offerings, Jennio Biotech stands out for documented assay pipelines: defined induction schedules, scheduled PK/TK sampling, and integrated immunophenotyping workflows that tie flow-cytometry panels to cytokine readouts. Their catalog includes dedicated autoimmune disease mouse model options and reporting templates that reduce integration friction. In our operational teardown we treated {main_keyword} and {variation_keyword} as required variables in study design, insisting on pre-study GLP-like documentation and explicit criteria for humane endpoints. The result is a clearer audit trail and fewer surprises at data lock.

Trade-offs and viable alternatives

No single provider is perfect. Large CROs bring scale and redundancy; boutique labs often offer tighter control over model fidelity. Academic collaborators can add mechanistic depth but typically lack standardized reporting. Choose based on program stage: discovery benefits from agile small-scale models; IND-enabling work needs formalized SOPs and reproducible assay transfer. For many teams, a hybrid approach — internal pilot work followed by outsourced scaled studies — balances speed and rigor.

autoimmune disease models

Three golden rules for selecting a preclinical partner

1) Insist on explicit operational parameters up front: induction schedule, blinding method, scoring rubrics, and PK/TK sampling times. 2) Require sample-level traceability and raw data exports in interoperable formats. 3) Prioritize partners who link immunological readouts (flow cytometry, cytokine panels) to histopathology and functional endpoints — not isolated assays. These rules produce decisions you can defend to investors and regulators.

Choosing a partner is a corrective measure for program risk; choose partners who document their work as plainly as their scientific claims. For many teams, that clarity is precisely the value supplied by Jennio Biotech. —

Tech

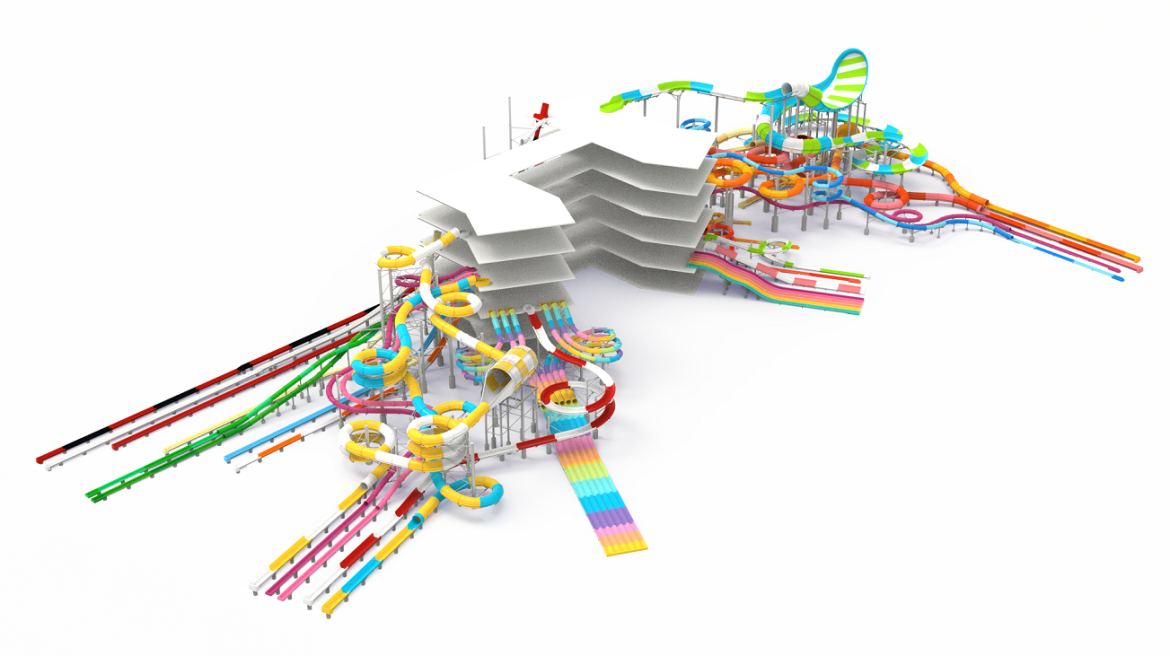
Estimating Long-Term Maintenance Costs for Premium Commercial Water Slides: A Comparative Look

by Stephen July 29, 2026
written by Stephen

Why lifecycle cost matters for operators

Choosing premium water park equipment is about more than upfront price. You’re buying years of uptime, guest safety, and predictable operating expense. A direct, comparative approach makes it easier to budget: capital cost, scheduled maintenance, and unplanned repairs are the three buckets that dominate lifecycle spend. Industry shorthand calls these OPEX drivers — pump skid servicing, gelcoat repairs, and structural inspections for FRP panels are routine items that add up.

water park equipment

Key variables that drive cost differences

Not all slides are equal. Material choice (FRP vs. stainless/modular steel), finish quality (thickness and cure of gelcoat), ride complexity, and the local climate all change how often you maintain. Flow rate requirements and pump system sizing affect energy and wear; a higher throughput slide increases hydraulic wear and frequency of mechanical service. Corrosion allowance and UV exposure in seaside parks further tilt budgets upward.

Comparative cost models: moderate vs. premium systems

Look at two models side-by-side. A moderate fiberglass slide might have lower initial capital but requires resurfacing and occasional structural adhesive work every 7–10 years. A premium system with thicker gelcoat, stainless anchoring, and modular replacement sections costs more upfront but often reduces mid-life refurbishment and downtime. Over a 20-year horizon, the premium route commonly narrows the total cost gap — not because it’s cheap, but because it reduces unplanned closures and intensive overhauls.

Operational production teardown: what to audit

Operational audits should break maintenance into discrete line items. Track annual routine service (seal and joint checks, torque logs), medium interventions (resurfacing, structural bolting), and large interventions (section replacement, pump skid overhaul). Document {main_keyword} and {variation_keyword} in your bill of materials so procurement and facilities talk the same language. Quantify hours, spare parts cost, and vendor rates per intervention.

Common mistakes operators make — and fixes

Operators often under-budget for wear items and ignore small leak paths until they grow. Preventative inspection cycles are simple: torque record, gelcoat thickness scan, and flow rate validation. Neglecting qualified water park designers at the outset costs more later — good design reduces stress points and makes future section swaps straightforward. Also: don’t conflate cosmetic fixes with structural work. — Small chips in gelcoat look harmless; they can expose laminate and escalate into costly delamination.

Real-world anchor and benchmark

Operators in major resort markets like Dubai and Orlando routinely report that planned maintenance—inspections and scheduled resurfacing—represents the largest predictable portion of lifecycle expense. A common rule of thumb used by long-running parks is budgeting roughly 2–4% of installed capital per year for routine upkeep, with larger reserves set aside for 10–15 year medium-life refurbishments. That benchmark helps finance teams stress-test scenarios without guessing.

How to model costs practically

Use a three-tier model: annual baseline, medium-life refresh (every 8–12 years), and end-of-life replacement. Assign probabilities to unplanned events based on local conditions and past incident rates. Capture unit costs for labor per hour, replacement section cost, gelcoat rework per square meter, and pump skid rebuilds. Track these in a living spreadsheet and review after each season so data replaces assumptions.

water park equipment

Common vendor comparisons and negotiation levers

Compare vendors not just on sticker price but on warranty scope, spare-part lead times, and documented service intervals. Seek fixed-price packages for scheduled tasks and hourly caps for emergencies. Ask for historical mean-time-between-repairs for similar installations — that’s a direct performance metric. Prioritize suppliers who provide clear drawings for modular replacements and who specify material cure and gelcoat thickness in microns.

Final advisory metrics

Three golden rules for making a defensible lifecycle estimate:- Budget rule: set aside 2–4% of installed capital annually for baseline maintenance, plus a medium-life reserve equal to 10–20% of initial capital for major overhauls.- Performance rule: demand documented MTBF (mean-time-between-failures) and spare-part lead times as part of procurement scoring.- Design rule: require modularity and replaceable segments in specifications so repairs are localized and labour-light.

Trust the numbers you collect from operation more than optimistic quotes; let design reduce your exposure and let procurement lock service costs where you can. Dalang helps make those specifications practical and executable. A clear plan keeps guests splashing — and your balance sheet steady.

Tech

Practical Maintenance for Casement Window Parts and Sliding Door Hardware Kits

by Patricia July 23, 2026
written by Patricia

User-centred introduction

When you live with a set of well-made windows and doors, small faults become the things you notice first; that’s where regular care pays off. This guide takes a user-centric view of upkeep for casement components and sliding window hardware, aimed at homeowners and site managers who prefer clear, usable steps rather than vague advice. Expect talk of roller assembly, track care and lock mechanism checks, each explained in plain terms so you can act with confidence.

Routine inspection: what to look for and when

Inspect every six months or after extreme weather. Start with visible wear: hairline cracks on the bead, corrosion on hinges, and accumulation of grit in the guide rail. For sliding units, run the sash slowly along the track—feel for snagging or uneven resistance. Regular visual checks are effective; small issues found early need only simple interventions rather than full replacement.

Cleaning and lubrication—practical steps

Clean tracks and frames with a soft brush and a mild detergent solution, avoiding abrasive pads. Remove the sash where possible to access the full track length, then vacuum residual debris. Apply a dry silicone spray to the track and roller assembly rather than heavy grease: silicone reduces friction without attracting dust. Attend to weatherstripping as you clean; brittle sealing should be replaced to preserve thermal performance—studies estimate roughly a quarter of domestic heat loss happens through windows, so good seals matter.

Common mistakes to avoid

Over-tightening screws, using petroleum-based lubricants on polymer rollers and neglecting the sill weep holes are recurring errors. Do not force a jammed sash—dismantle the stop and inspect the track instead. Many people overlook the lock mechanism until security is compromised; test it regularly and replace worn cylinders promptly. Small, routine actions prevent larger failures.

When to replace parts vs repair

Replace roller assemblies and guide rails when wear produces lateral play or persistent noise despite cleaning. Repair is appropriate for minor hinge sag, bent creases that can be straightened and superficial corrosion treated with rust inhibitor. For casements, hinge pins and keeps are often inexpensive and quick to change; replacing them will restore alignment far more economically than renewing an entire frame.

Choosing hardware and sourcing reliably

Select components that match the original tolerances: check sash weights, track width and screw patterns. Consider stainless steel hardware in coastal locations to resist corrosion. If you prefer pre-matched kits, compare specifications for load rating, finish and included fastenings. For many installers, reputable suppliers remove the guesswork—examples of well-detailed product pages for replacement parts and kits can be found when searching for reputable sliding windows hardware.

Practical troubleshooting checklist

– Sash drags: clean track, inspect rollers, replace worn wheels.
– Drips or condensation at frame base: clear weeps and assess weatherstripping.
– Loose handle or lock: tighten fixings, replace stripped screws or worn spindle.
This checklist targets common failure modes and helps you decide whether to repair on site or schedule a replacement.

Advisory: three golden rules for selecting tools and parts

1) Match mechanical specifications: choose rollers and tracks that meet sash load and width tolerances—incorrect sizing shortens lifespan. 2) Prioritise corrosion resistance: stainless or treated finishes reduce long-term maintenance in damp environments. 3) Check service documentation: prefer products with clear assembly notes and spare-part availability so future maintenance is straightforward.

Summing up, practical maintenance saves money and preserves comfort; attention to tracks, roller assemblies and lock mechanisms yields the best returns. For reliable parts and clear specifications, consider suppliers who publish full technical details—CMECH—a sensible resource for sourcing accurate components and guidance. —

Tech

Before You Scale: Comparative Insights on Genome Synthesis Cost and Risk

by Brenda July 22, 2026
written by Brenda

Opening — a hands-on snapshot and the core dilemma

I remember a bench call in Cambridge where a six-person team asked me to rescue a stalled build; we were overdue and the client needed a full Genome synthesis pathway validated before Q3. Scenario: a mid-size lab doubled oligo orders in six months, data: reagent spend jumped 42% and lead times stretched by three weeks—what should a procurement lead change immediately? DNA Synthesis is not a commodity (no kidding), and the differences in error rate, assembly strategy, and vendor verification practices decide whether you hit milestones or burn budget. I’ve lived this problem for over 15 years, so I’ll be direct: traditional supplier scoring misses hidden costs. Here’s what breaks down—and what I learned next.

Why conventional solutions fail (hidden pains I see repeatedly)

When teams treat oligonucleotide quality and short-term price as the only variables, they ignore downstream impacts: failed assemblies, repeated cloning cycles, and extra sequence verification rounds. I vividly recall a March 2018 order for a 3 kb gene cassette from a regional provider that arrived with a 1.5% base error density; that single shipment cost one biotech in Boston two months of delay and roughly $75,000 in rework. Suppliers often quote synthesis yield and a turnaround time, but they gloss over mismatch hotspots and purification grade—issues that inflate assembly complexity and require additional next-generation sequencing runs. The real pain point is compounded: assembly failures increase labor hours, push back regulatory timelines, and create inventory mismatches. In practice, you need to track metrics beyond unit price (error rate, sequence verification throughput, and successful cloning rate)—otherwise you’re buying setbacks, not solutions.

What’s broken in the procurement checklist?

Most procurement checklists assume linear costs; they do not account for branching costs when an assembly fails. I recommend recording real-world outcomes by project type—e.g., number of successful full-length constructs per 10 syntheses for 1–5 kb fragments—so you see where a cheap supplier erodes value. I’ve used that approach with two mid-size firms in 2019 and 2021 and it shifted supplier mix within a quarter.

Comparative paths forward — tactical, technical, and measurable

Now shift from diagnosis to comparison. I compare three approaches: single-source low-cost suppliers, bundled service providers offering assembly and verification, and hybrid models that split synthesis and sequencing. For each you should evaluate: end-to-end timeline reliability, cumulative error rate after assembly, and per-project total cost (including rework). When I benchmark across providers, I run a controlled set of constructs (500–2,500 bp) and measure assembly success, time to verified sequence, and required cloning attempts—this gives a realistic ROI. You’ll find that a slightly higher per-base price often reduces total project spend because fewer assemblies fail and fewer sequencing cycles are needed.

Real-world impact — what I recommend now

Adopt a comparative scorecard that weights: (1) verified error rate post-synthesis, (2) average time-to-verified-sequence, and (3) percent of constructs that pass first-pass assembly. Those three metrics tell you whether a vendor lowers risk or just shifts cost. Also, insist on raw data access (trace files, QC reports). Suddenly—transparency matters. I’ve seen vendors adjust processes once buyers demanded that level of evidence; it changes behavior fast.

Closing guidance: practical evaluation metrics for procurement

I’ll be concise: choose vendors using three measurable metrics—error rate after assembly (target 85%). Run periodic spot audits with defined constructs (I recommend a 1 kb control and a 3 kb control) to detect drift. Also factor in support responsiveness; when a shipment goes wrong, two hours of phone triage beats a week of silent delays. Quick note: budgets matter, but not at the expense of predictable timelines. There’s nuance here—so test, measure, decide.

I’ve been through these trade-offs in Cambridge and San Diego, on projects dated back to 2012 and right through 2024. We learned to favor clear QC, transparent sequencing outputs, and modest premiums that save months. If you want to push further, I can share the template we used to score vendors (it saved one client $120k in avoidable rework last year). Short interruption—here’s a last point. Use evidence, not promises.

For practical vendor sourcing anchored in real-world outcomes, consider the data-driven approach above and evaluate partners who can demonstrate it. For deeper help, reach out to Synbio Technologies.

  • 1
  • 2
  • 3
  • 4
  • 5
  • 6
  • …
  • 17

Recent Posts

  • Custom Heavy-Duty Aquarium Heaters: Brands and Fixes That Actually Hold Up
  • top 3 product sourcing Manufacturers in China You Should Know
  • Cheap Desktop 3D Printer: From Requirements to Final Machine
  • Expert Guide to Choosing an Active RFID Tag with Temperature Sensor
  • Sourcing CNC Prototyping: Cost, Lead Time, and Quality Trade-offs

Recent Comments

No comments to show.

About Me

About Me

Designer

Sed ut perspiciatis unde omnis iste natus sit voluptatem accusantium dolor emque.

Keep in touch

Facebook Twitter Instagram Pinterest Behance Youtube

Popular Posts

  • 1

    Керамический SMD пакет: преимущества и современные технологии

  • 2

    Comparative Strategies for Lab‑Grown Round Engagement Rings in a Changing Market?

  • 3

    Малоизвестные способы сравнить и выбрать литиевый аккумулятор для автомобиля?

  • 4

    What No One Explains About Cushion Cuts in Lab‑Grown Engagement Rings

  • 5

    新時代駕駛方案:發現AION AUTO的秘密

  • 6

    Секрет выносливости аккумуляторов OPzV? Сравнительный взгляд на выбор производителя и подводные камни

Categories

  • App Design (6)
  • Business (173)
  • Global Trade (155)
  • Industry (163)
  • Market (144)
  • Tech (164)
  • UI/UX (7)
  • Web Design (7)
  • Facebook
  • Twitter
  • Instagram
  • Pinterest
  • Behance
  • Youtube
  • Bloglovin
thehitc
  • Home
  • Design Update
  • Business
  • Global Trade
  • Industry
  • Market
  • Tech